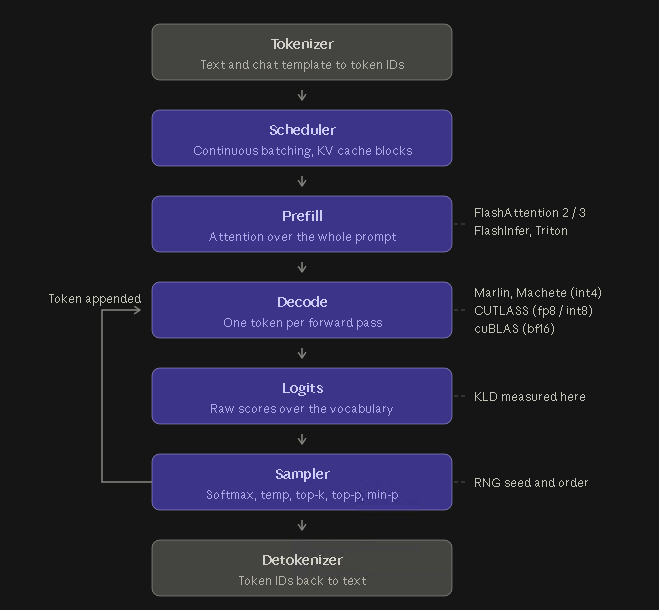
A technical deep-dive on the Level1Techs forum has struck a chord with the AI community, racking up hundreds of upvotes on Hacker News. The post tackles a complaint almost every self-hoster has heard: you download a model everyone raves about, run a local build, and it feels noticeably dumber than the demos.
The author argues the gap is rarely the model itself. Every hardware and software stack executes inference differently: mixed GPU generations, different instruction sets, and implementation quirks all change how logits are calculated. Even the same weights can behave differently between setups, so the reference implementation benchmarks rarely transfer to your machine.
The post offers practical fixes. Run standard benchmarks that match your actual workload instead of a few zero-shot prompts, and use the sampler settings and chat template specified on the model card. Setting temperature too low, for example, can cause models to loop on reasoning tokens. The takeaway: your local LLM is probably fine, and small config fixes often matter more than chasing bigger models.