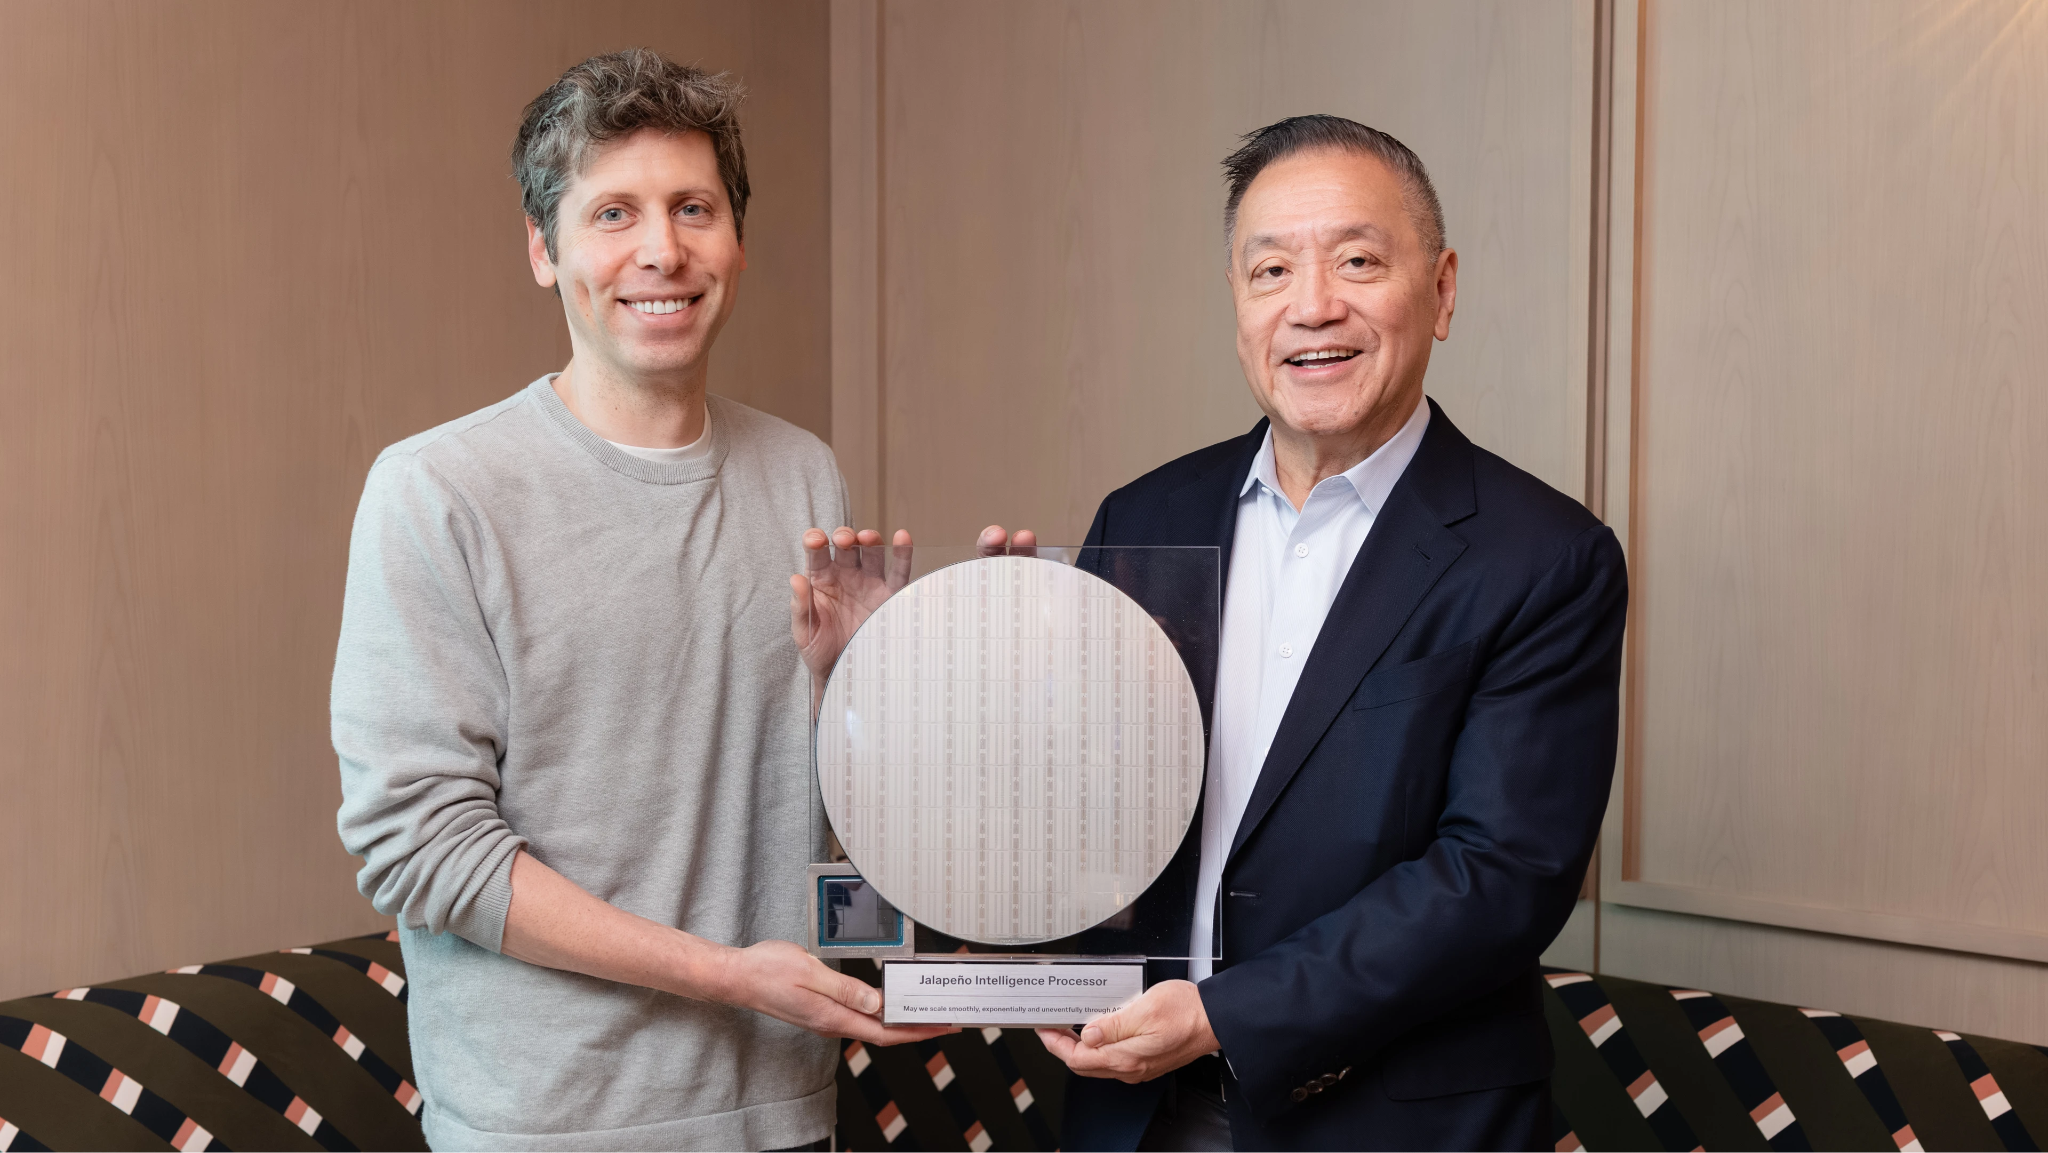
OpenAI unveiled Jalapeño, its first custom inference chip, at Hot Chips. Built with Broadcom from a blank slate for LLM inference, it went from initial design to tape-out in about 16 months. SemiAnalysis was invited to benchmark the chip in OpenAI's labs with its InferenceX suite, and the results are striking: Jalapeño beats every Nvidia, AMD and Google chip tested across several top open-source models.
The headline number is throughput per megawatt. OpenAI is datacenter power-limited, so tokens per MW is revenue, and Jalapeño leads on perf-per-watt in almost every scenario without being tuned for any single workload. At low concurrency it hit more than 700 tokens per second per user on DeepSeek R1, and around 1,400 tokens per second per user on Kimi-K2.5 and GPT-OSS, all with plain single-token prediction, no speculative decoding and no disaggregation tricks.
Jalapeño is a generalized inference chip with HBM4 memory, not a narrow OpenAI-only part, and SemiAnalysis says it should really be compared with Nvidia's upcoming Rubin rather than Blackwell. First production tokens are due soon as OpenAI scales toward 100MW of deployments. For founders, cheaper and more efficient inference is a direct win for AI product margins.