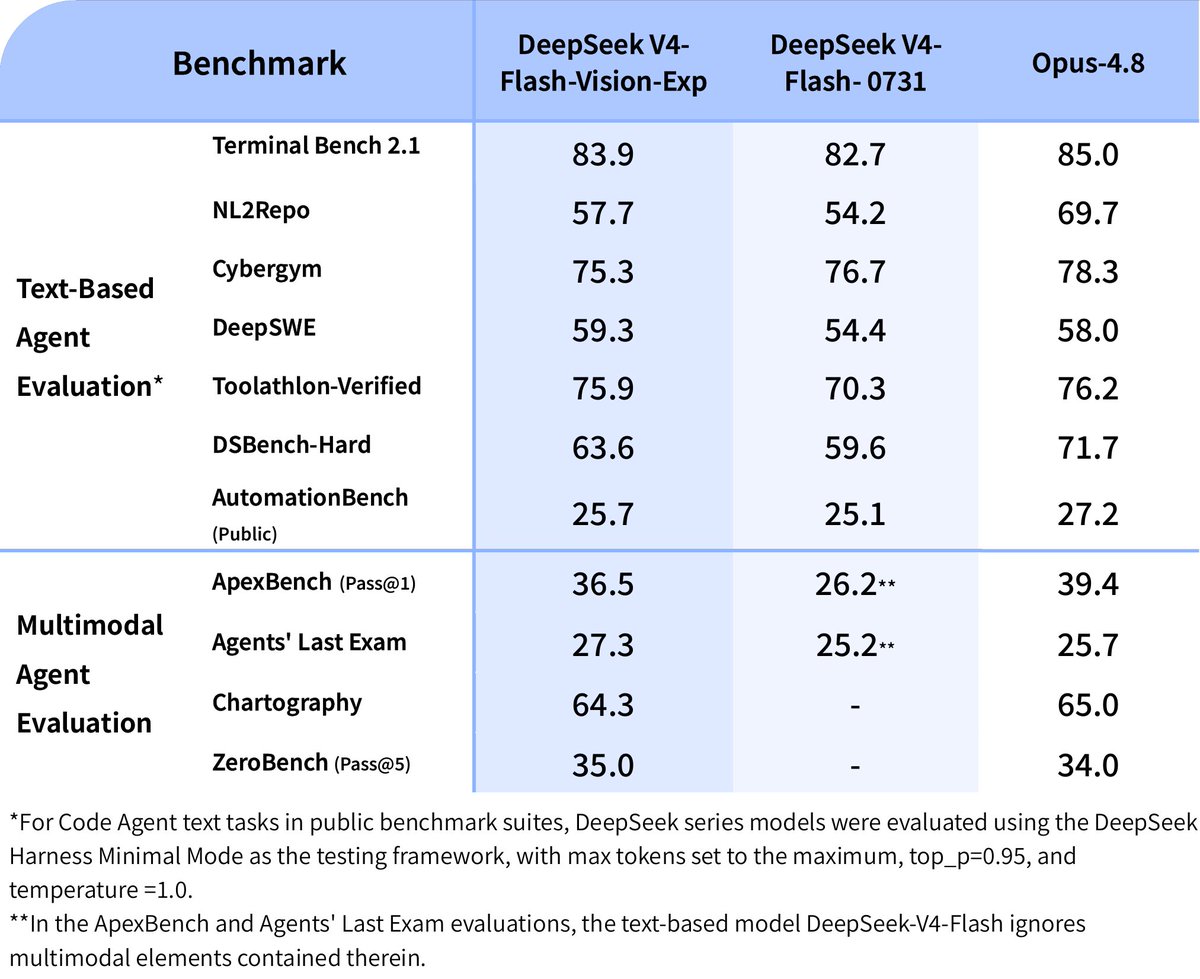
DeepSeek has launched DeepSeek-V4-Flash-Vision-Exp, an experimental multimodal model now live on the DeepSeek API Platform. The company announced the release on X, positioning the new model as a vision-capable sibling to its V4-Flash flagship. Developers can access it immediately through the API, with no waitlist or special application required, making it one of the fastest ways to test a frontier-class vision model.
According to the announcement, the new model matches DeepSeek-V4-Flash on text capabilities, including agents, reasoning, and world knowledge. The biggest gains come on multimodal agent benchmarks, where V4-Flash-Vision-Exp delivers a major improvement. That means it can interpret screenshots, diagrams, charts, and real-world images while still handling multi-step agentic tasks that trip up many vision models.
For founders building AI products, this matters. A vision model that retains strong agentic reasoning unlocks use cases in document processing, UI automation, visual QA, and screen-reading assistants, all without switching between separate text and vision models. The experimental tag signals rapid iteration, and DeepSeek is likely to refine the model based on developer feedback. Documentation and example workflows are already available in the DeepSeek API guides.