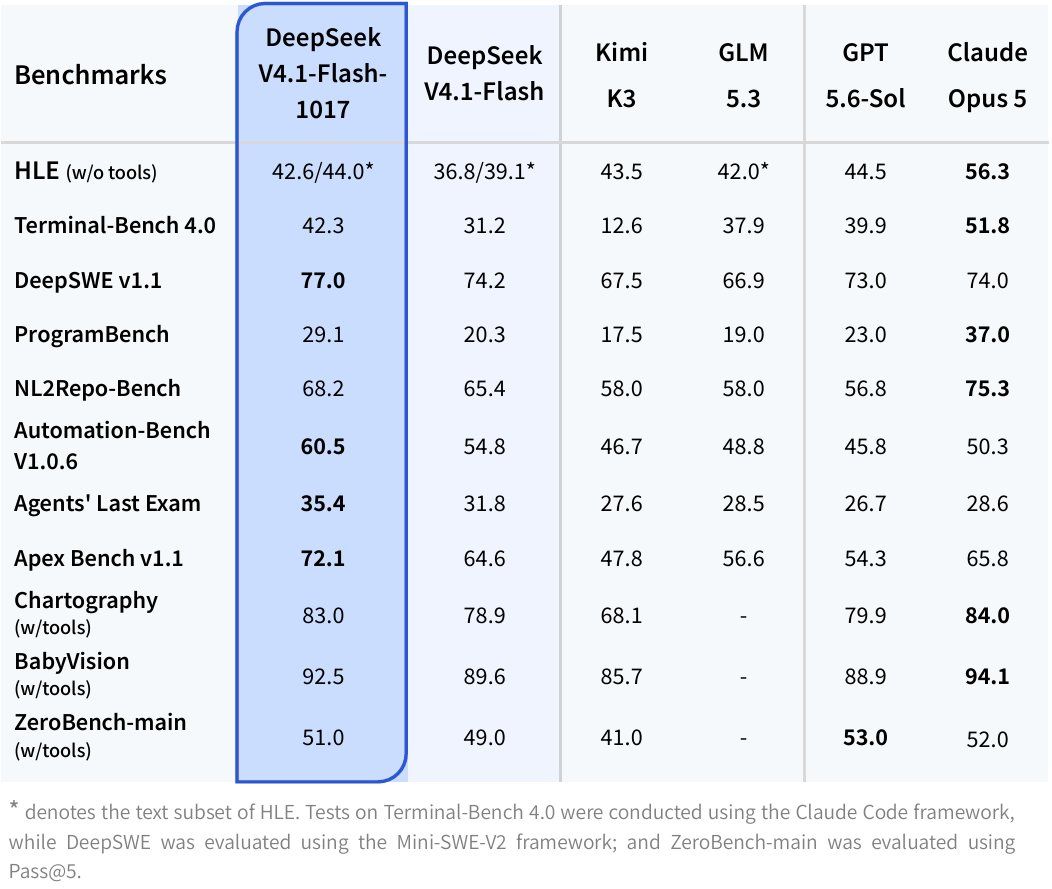
DeepSeek has pushed out DeepSeek-V4.1-Flash-1017, an open-weight refresh of its small-but-fast model family, and the release shot straight to the top of Hacker News with more than 900 points. The company calls it a Pareto improvement over the previous version: stronger benchmark performance, faster task completion and shorter outputs, with no cost regression. It is live now on the DeepSeek website, app and API.
The interesting part for builders is how it was trained. DeepSeek says V4.1-Flash-1017 uses reinforcement learning with self-feedback to improve end-to-end project development, from game creation through to 3D modeling. The company also published the weights, placing the model on Hugging Face and ModelScope so teams can self-host instead of renting inference. DeepSeek lists optimized support for its own Harness tooling plus Tencent CodeBuddy and WorkBuddy, and recommends upgrading DeepSeek Harness to v0.2.1-rc.1 or later for the best experience.
For founders the takeaway is cost and lock-in. An openly licensed, high-throughput model that closes much of the gap on the previous generation means agent workloads can move onto cheaper self-hosted inference, while API users get a straightforward upgrade path without rewriting prompts. The usual caveat applies: these are vendor-reported benchmarks, and the community will want independent evaluations before fully trusting the Pareto framing.